Cross-Chain Recovery Is Part of the Route
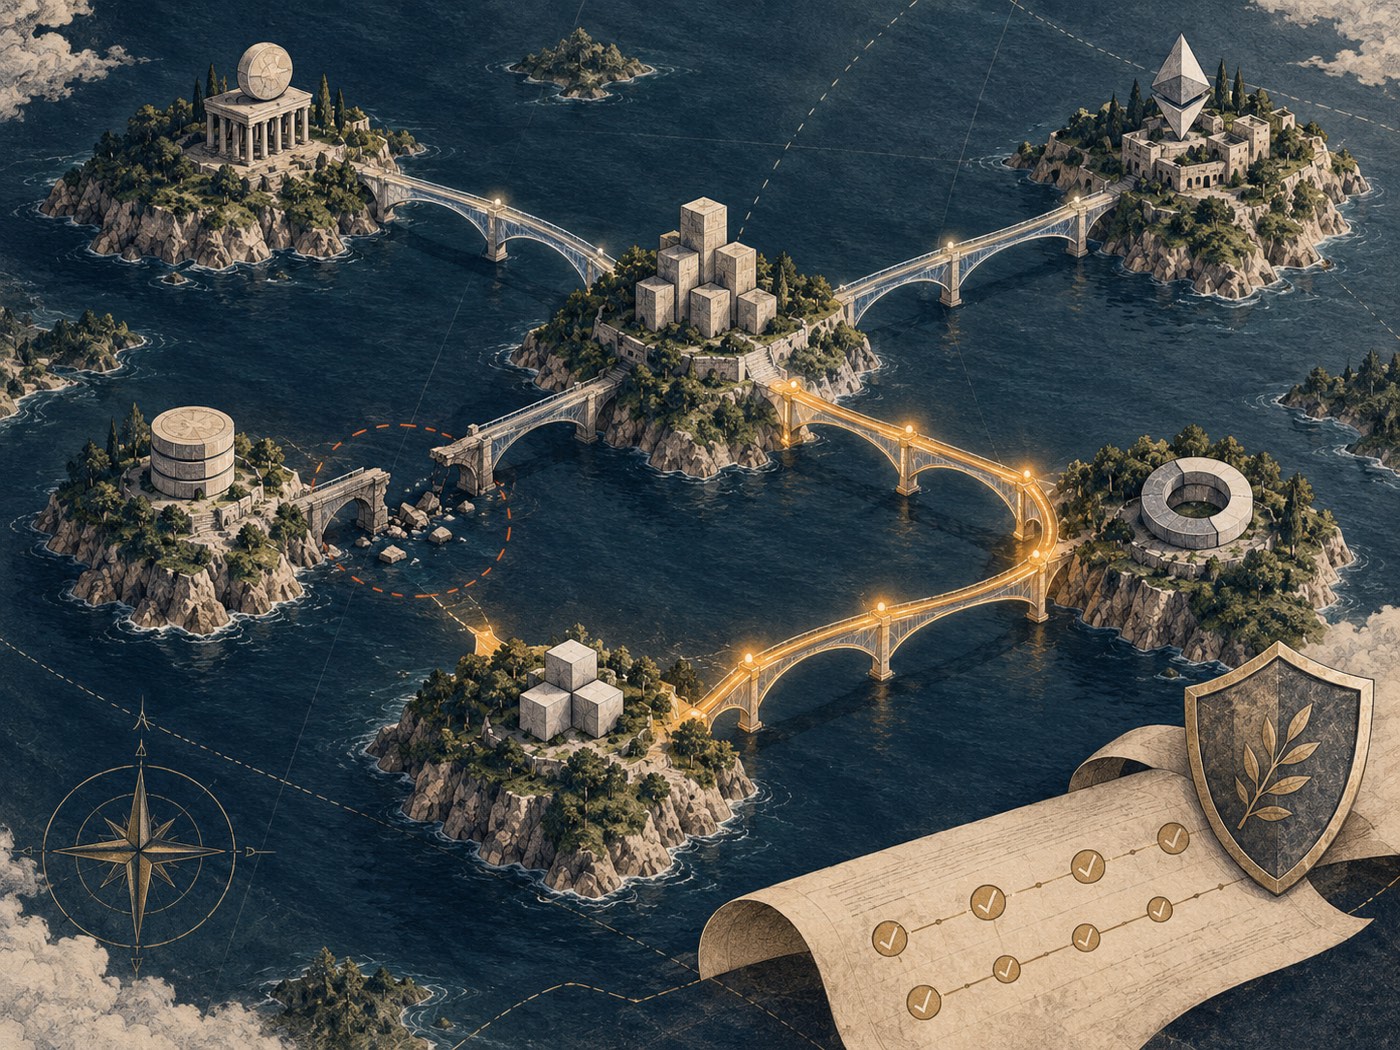
Cross-chain execution earns trust through its recovery path. Every route needs clear controls for detection, containment, reconciliation, and restart.
What the NEAR Intents incident brought into focus
On October 1, NEAR Intents paused parts of its cross-chain service after an exploit tied to the interaction between its Omni deposit and withdrawal infrastructure and a NEAR Intents smart contract. The Block reported an initial loss of about $3.8 million and a promise to compensate affected users. Decrypt described the pause across cross-chain swaps, while Bitquery later traced approximately $3.87 million across BNB Chain, Ethereum, Bitcoin, and exchange addresses.
The story moved quickly. The team patched the contract-side flaw, restricted deposits and withdrawals across several networks, and communicated a recovery process. A later public update reported that the stolen funds had been returned in full. The sequence matters because the operational response became part of the user experience: detect, pause, trace, communicate, reconcile, and resume.
The incident also gives the market a useful distinction between route convenience and route quality. A smooth cross-chain interface can hide many operational dependencies. A trustworthy interface makes those dependencies visible enough for users and operators to make good decisions.
Cross-chain routes have several risk surfaces
A user sees an input asset, a destination asset, and an expected amount. The route may also involve a deposit vault, a solver, a bridge or messaging layer, a destination venue, and several confirmation policies. Each component adds a state transition that deserves a check.
Three questions belong in route evaluation:
- Where does value sit during execution? Temporary custody, hot-wallet exposure, and settlement timing affect the route's operational risk.
- What event allows the next step? A signed note, block confirmation, oracle update, solver quote, or destination settlement should have an explicit validity window.
- What happens when one component is paused? A route should define its fallback, refund, claim, or manual reconciliation path before users need it.
These questions convert a vague security promise into observable execution data. They also make route comparisons more useful for traders who care about finality and recoverability as much as price.
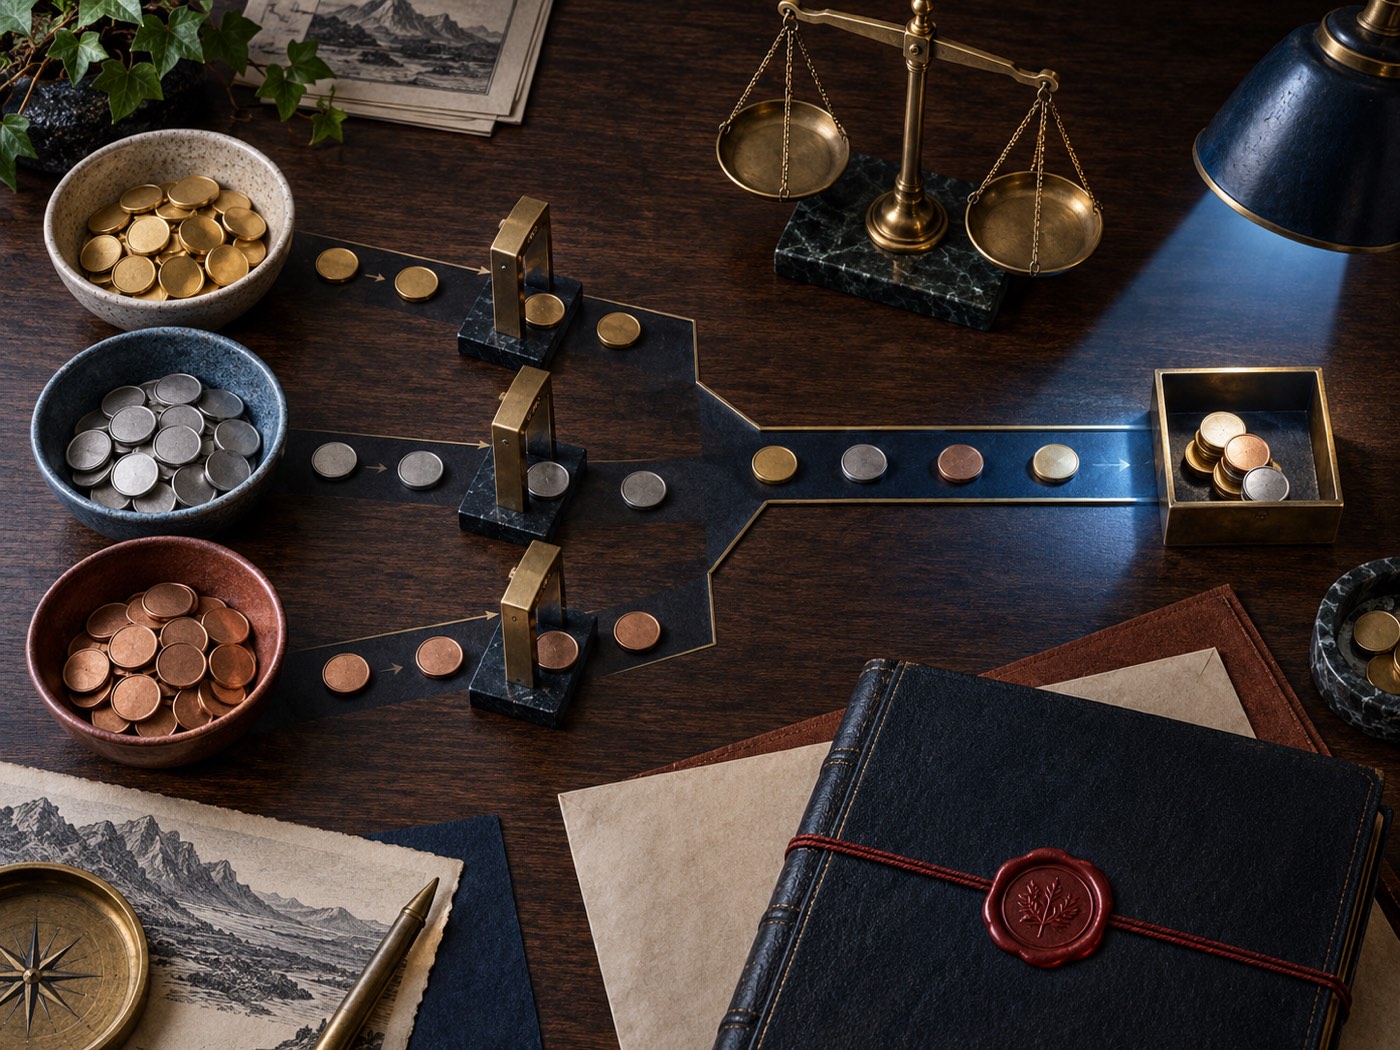
Four controls that turn an incident into an operating standard
1. Separate route selection from route authorization
Price discovery can consider many venues and liquidity sources. Authorization should still apply strict limits to each asset, chain, vault, and settlement action. A quote can be attractive while the associated route is temporarily outside its operating policy.
Per-route limits, short-lived approvals, and independent monitoring reduce the chance that one compromised seam can authorize a broad set of withdrawals.
2. Contain the smallest affected surface
Fast containment works best when operators can pause a chain, asset, venue, or action independently. A global shutdown protects funds, yet it also increases user disruption and makes recovery harder to explain. Granular circuit breakers preserve healthy paths while an affected component is examined.
Containment should publish the scope, timestamp, affected actions, and next review condition. This turns a pause into a state users can understand.
3. Reconcile every state transition
After an incident, the team needs a ledger that connects deposits, authorizations, payouts, destination settlement, and user claims. The ledger should answer three practical questions:
- Which user balance is affected?
- Which route step created the discrepancy?
- What evidence proves that the balance is safe to release or refund?
This record supports both internal recovery and public communication. It also helps normal operations because the same data can power route status, pending-transfer notices, and settlement receipts.
4. Make restart a measured event
Restoring service should follow explicit gates: patch validation, balance reconciliation, monitoring coverage, small-value canaries, and a clear rollback path. A route that resumes with a known cap and visible status gives operators room to learn while keeping exposure controlled.
What this means for liquidity routing
Liquidity routing is becoming a decision about more than the highest quoted output. A production route should weigh:
- expected output after fees and slippage
- confirmation and settlement time
- liquidity depth at the requested size
- custody and bridge dependencies
- route health and current limits
- refund and recovery options
These inputs help a router select paths that can complete under real conditions. They also give users a reason to trust the result because the interface explains the choice in terms they can verify.
The NEAR Intents episode shows how quickly a route can move from normal execution to incident response. It also shows why recovery design deserves the same product attention as quote speed. Users remember whether they could understand the pause, locate their funds, and see the path back to settlement.
OneSwap and the next execution standard
OneSwap is built for users who need a clear path across fragmented liquidity. A useful cross-chain experience brings together route discovery, execution details, and status information so traders can evaluate a swap before they commit.
The next step for the category is operational clarity at every stage: show the route, surface the meaningful dependencies, apply limits before execution, and keep a reliable record after settlement. That approach gives liquidity routing a stronger foundation as stablecoins, tokenized assets, and new chains expand the number of possible paths.
Explore cross-asset execution at oneswap.ai.